OCR PDF — make scanned PDFs searchable
Run OCR on a scanned or image-only PDF to recognize its text and create a searchable PDF — free and entirely in your browser. Your file is never uploaded to a server.
How to OCR a PDF
- Open the OCR tool and add your scanned PDF — drag and drop it, or click “Choose files.”
- Choose your output. Create a searchable PDF (keeps the original look, adds selectable text), export the recognized text as a .txt file, or both.
- Run OCR & download. Recognition runs on your device. Review the result, then choose Download to save the selected outputs.
OCR a PDF without uploading it
The document tools process file contents in your browser rather than uploading them for processing. Working files remain in page memory; downloads remain wherever you save them. Informational pages may load ads or analytics; the document-opening page excludes them. Read the privacy policy for details.
Scanned tables? Convert them directly
To turn a scanned table into a spreadsheet, add it straight to the free PDF to Excel or PDF to CSV converter: pages without text are read with the same on-device OCR during the conversion, so you don’t need to run OCR here first.
Recognize text in JPG and PNG photos
The OCR upload picker accepts PDFs, JPEG and PNG images. Export a searchable PDF, a plain-text file or both. Choose the text language first: 45 languages are bundled, including Chinese, Japanese, Korean, Arabic, Hindi and most European languages. Clear scans work best; handwriting, skew, blur and small text can reduce accuracy. Keep this tab open while processing. You can browse the tool catalog and return with View result when it is ready.
Worked example: turn an image-only page into searchable text
Download the fictional scanned PDF or the equivalent PNG photo sample. The PDF contains a page image, with no initial selectable text layer. Its short English note is deliberately clear so you can learn the workflow before trying a difficult scan.
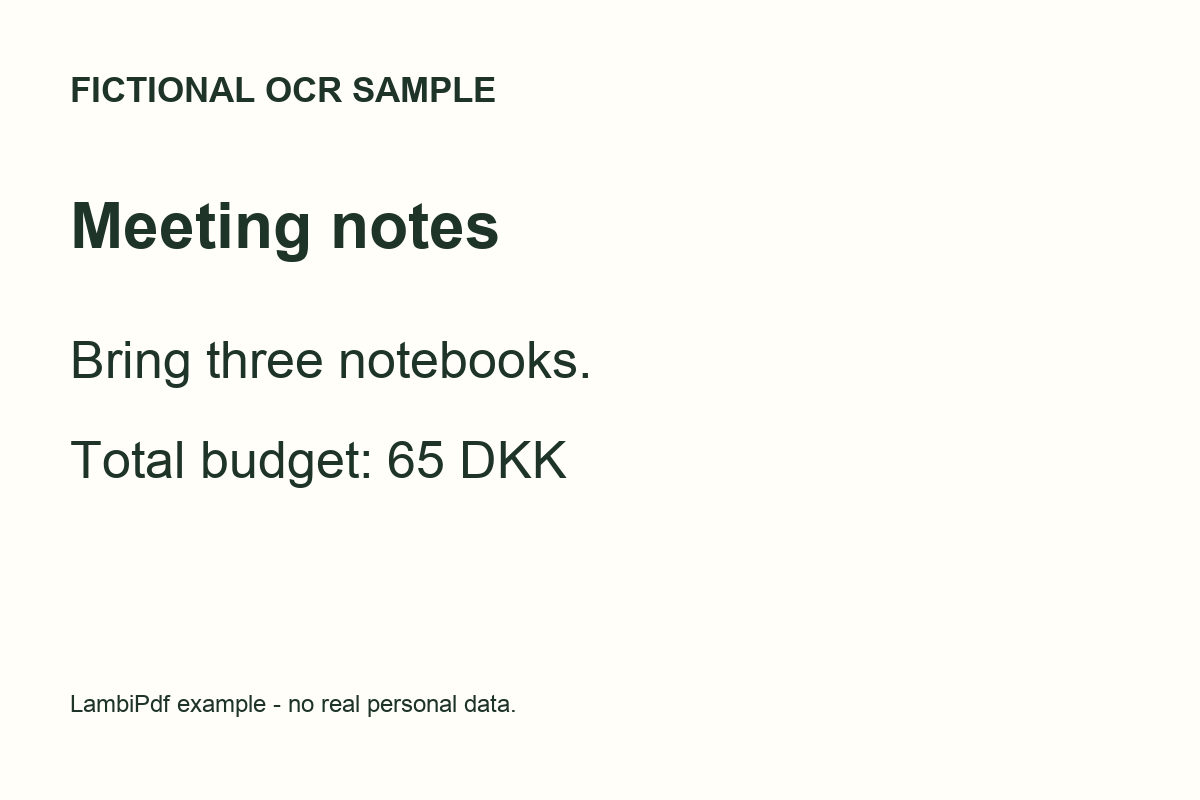
- Open OCR and choose the downloaded PDF or PNG. Select searchable PDF, recognized text, or both.
- Run OCR and keep the processing tab open. The engine loads locally served assets, then recognizes the page. You may browse the tool catalog while it works and return with View result.
- Review the result before downloading. Look for the sentence “Bring three notebooks.” and the amount “65 DKK”. Search for a word in the downloaded searchable PDF and compare the recognized text with the image.
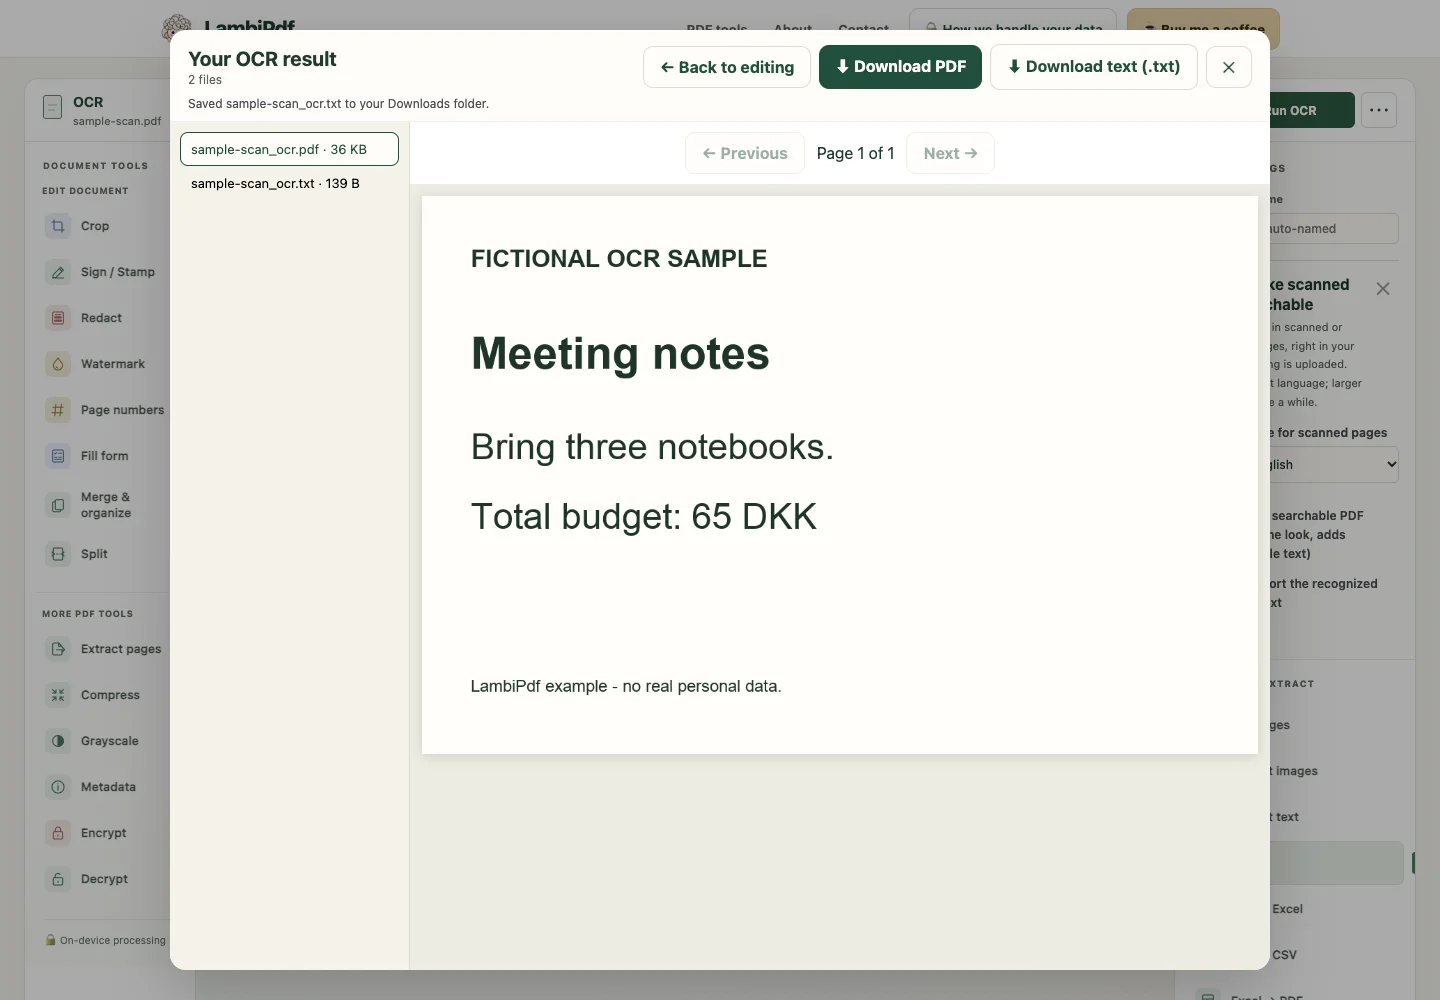
Compare the recognized TXT output and searchable PDF output. The searchable file keeps the page image and adds an invisible text layer. It does not turn the page into editable paragraphs or reconstruct an Excel table.
Why OCR sometimes takes longer than other tools
Recognizing characters is more work than copying PDF pages. The first run also needs the recognition engine and language assets. Page count, image size, device memory and browser performance all matter. A slower result is not evidence that your document is being uploaded. Cancel if needed; retry a smaller page range or a clearer, sensibly sized scan.
What to check on a difficult scan
- Rotate sideways pages before recognition and avoid photographs taken at a steep angle.
- Use a clear original with readable characters. Upscaling a blurred image does not restore lost detail.
- Check 0/O, 1/I, decimal marks, dates and line breaks. One wrong character can change an account reference or amount.
- Handwriting, decorative fonts, multiple columns and a wrongly chosen text language can reduce accuracy. Pick the document's language before you run OCR.
If a PDF already has selectable text, try Extract text first. OCR is useful for image-only pages, and its output always needs human review.
More free PDF tools
OCR PDF — FAQ
Is OCR on LambiPdf free?
Yes — it's completely free, with no sign-up and no watermark.
Are my files uploaded when I run OCR?
No. OCR runs entirely in your browser using an offline engine; file contents are not uploaded for processing.
What do I get — a searchable PDF or plain text?
Either or both. You can create a searchable PDF that keeps the original look with a selectable text layer, and also export the recognized text as a .txt file.
Which languages are supported?
45 languages: English, most European languages (French, German, Spanish, Italian, Portuguese, Dutch, Polish and more), Russian, Ukrainian, Greek, Arabic, Hebrew, Hindi and other Indian languages, Thai, Chinese, Japanese and Korean. Choose the text language before running OCR; English is always included. Recognition accuracy is best on clear, high-resolution scans.